Bronze V
1,362 Elo
- #8,791 on the ladder
- −1 today · −22 this week
- Peak 1,420
13 Elo to Bronze IV
 bestofgithub.dev
An Extensible Toolkit for Finetuning and Inference of Large Foundation Models. Large Models for All.
OptimalScale/LMFlow is #8,791 on the bestofgithub Elo ladder, in Bronze V, with a rating of 1,362 (−22 this week). It has 8,481 stars.
1,362 Elo
8,481
 Maintainer? Show your league in your README
Card: your league's emblem, from Copper to Legendary
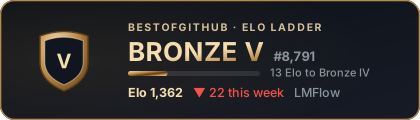
[](https://bestofgithub.dev/repo/OptimalScale/LMFlow)Flat: fits beside your other badges
[](https://bestofgithub.dev/repo/OptimalScale/LMFlow)git clone https://github.com/OptimalScale/LMFlow.gitCode and documentation to train Stanford's Alpaca models, and generate the data.
git clone https://github.com/tatsu-lab/stanford_alpaca.gitGoogle AI 2018 BERT pytorch implementation
git clone https://github.com/codertimo/BERT-pytorch.gitA framework for few-shot evaluation of language models.
pipx install lm_evalAn open source implementation of CLIP.
git clone https://github.com/mlfoundations/open_clip.gitNano vLLM
git clone https://github.com/GeeeekExplorer/nano-vllm.gitRWKV (pronounced RwaKuv) is an RNN with great LLM performance, which can also be directly trained like a GPT transformer (parallelizable). We are at RWKV-7 "Goose". So it's combining the best of RNN and transformer - great performance, linear time, constant space (no kv-cache), fast training, infinite ctx_len, and free sentence embedding.
git clone https://github.com/BlinkDL/RWKV-LM.gitLoading README…