Gold V
1,532 Elo
- #4,734 on the ladder
- +6 today · +32 this week
- Peak 1,532
6 Elo to Gold IV
 bestofgithub.dev
Crawlee—A web scraping and browser automation library for Python to build reliable crawlers. Extract structured data with LLMs via Pydantic AI, or control the browser in natural language with Stagehand. Works with BeautifulSoup, Parsel, Playwright, and raw HTTP. Download HTML, PDF, images, and other files. Proxy rotation included.
apify/crawlee-python is #4,734 on the bestofgithub Elo ladder, in Gold V, with a rating of 1,532 (+32 this week). It has 9,675 stars, 20 gained in the last week.
1,532 Elo
9,675
 Maintainer? Show your league in your README
Card: your league's emblem, from Copper to Legendary
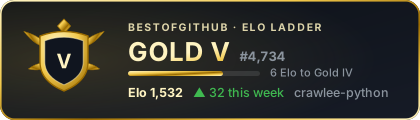
[](https://bestofgithub.dev/repo/apify/crawlee-python)Flat: fits beside your other badges
[](https://bestofgithub.dev/repo/apify/crawlee-python)git clone https://github.com/apify/crawlee-python.gitCrawlee—A web scraping and browser automation library for Node.js to build reliable crawlers. In JavaScript and TypeScript. Extract data for AI, LLMs, RAG, or GPTs. Download HTML, PDF, JPG, PNG, and other files from websites. Works with Puppeteer, Playwright, Cheerio, JSDOM, and raw HTTP. Both headful and headless mode. With proxy rotation.
git clone https://github.com/apify/crawlee.gitOfficial Crawl4AI Cloud: a hosted web scraping, extraction, and search API for AI agents. Free API key, 1,000 credits a month, no card. Fully open source: this repo is the Apache-2.0 crawler that powers it, and you can self-host it.
pipx install Crawl4AIScrapy, a fast high-level web crawling & scraping framework for Python.
brew install scrapyElegant Scraper and Crawler Framework for Golang
git clone https://github.com/gocolly/colly.gitA Smart, Automatic, Fast and Lightweight Web Scraper for Python
git clone https://github.com/alirezamika/autoscraper.gitnewspaper3k is a news, full-text, and article metadata extraction in Python 3. Advanced docs:
git clone https://github.com/codelucas/newspaper.gitLoading README…