Platinum IV
1,668 Elo
- #2,593 on the ladder
- +4 today · +81 this week
- Peak 1,670
1 Elo to Platinum III
 bestofgithub.dev
FlashInfer: Kernel Library for LLM Serving
flashinfer-ai/flashinfer is #2,593 on the bestofgithub Elo ladder, in Platinum IV, with a rating of 1,668 (+81 this week). It has 6,928 stars, 52 gained in the last week.
1,668 Elo
6,928
 Maintainer? Show your league in your README
Card: your league's emblem, from Copper to Legendary
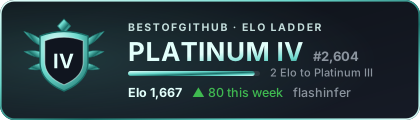
[](https://bestofgithub.dev/repo/flashinfer-ai/flashinfer)Flat: fits beside your other badges
[](https://bestofgithub.dev/repo/flashinfer-ai/flashinfer)git clone https://github.com/flashinfer-ai/flashinfer.gitCUDA Templates and Python DSLs for High-Performance Linear Algebra
git clone https://github.com/NVIDIA/cutlass.gitTensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
git clone https://github.com/NVIDIA/TensorRT-LLM.gitAccelerate local LLM inference and finetuning (LLaMA, Mistral, ChatGLM, Qwen, DeepSeek, Mixtral, Gemma, Phi, MiniCPM, Qwen-VL, MiniCPM-V, etc.) on Intel XPU (e.g., local PC with iGPU and NPU, discrete GPU such as Arc, Flex and Max); seamlessly integrate with llama.cpp, Ollama, HuggingFace, LangChain, LlamaIndex, vLLM, DeepSpeed, Axolotl, etc.
git clone https://github.com/intel/ipex-llm.gitA PyTorch implementation of the Transformer model in "Attention is All You Need".
git clone https://github.com/jadore801120/attention-is-all-you-need-pytorch.gitA Python framework for GPU-accelerated simulation, robotics, and machine learning.
git clone https://github.com/NVIDIA/warp.gitLoading README…