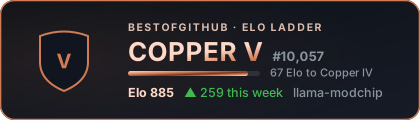
Copper V
885 Elo
- #10,057 on the ladder
- +18 today · +258 this week
- Peak 885
66 Elo to Copper IV
 bestofgithub.dev
Run 284B DeepSeek-V4-Flash (<59GiB RAM: 41.1 cold pp, 9.1 N=1 tg, up to 25.3 spec tok/s) & 30B MoEs (22.4 N=1 / 111.6 spec tok/s) on 64GB CPU (0 GPUs).
synchopate/llama-modchip is #10,057 on the bestofgithub Elo ladder, in Copper V, with a rating of 885 (+258 this week). It has 1,267 stars.
885 Elo
1,267
 Maintainer? Show your league in your README
Card: your league's emblem, from Copper to Legendary
[](https://bestofgithub.dev/repo/synchopate/llama-modchip)Flat: fits beside your other badges
[](https://bestofgithub.dev/repo/synchopate/llama-modchip)git clone https://github.com/synchopate/llama-modchip.gitRun models larger than your RAM or VRAM by streaming MoE experts from SSD. Built on llama.cpp.
git clone https://github.com/wici-ai/inferssd.gitDistribute and run LLMs with a single file.
git clone https://github.com/mozilla-ai/llamafile.gitLoading README…